Introduction
AI-powered WordPress plugins are evolving beyond simple text generation. Modern applications can analyze large documents, manage WooCommerce workflows, retrieve information from multiple sources, call external tools, and execute complex, multi-step AI tasks.
These capabilities introduce an important challenge: managing token consumption without sacrificing output quality.
Tokens are the units that language models process. Depending on the model and provider, tokens can represent portions of words, complete words, punctuation, or other elements of an input. AI requests may consume tokens through instructions, conversation history, retrieved documents, tool definitions, generated responses, and additional model-specific processing.
Without a clear token budget, a WordPress plugin can send oversized prompts, exceed a model's context window, generate unnecessarily long responses, or consume more API credits than expected.
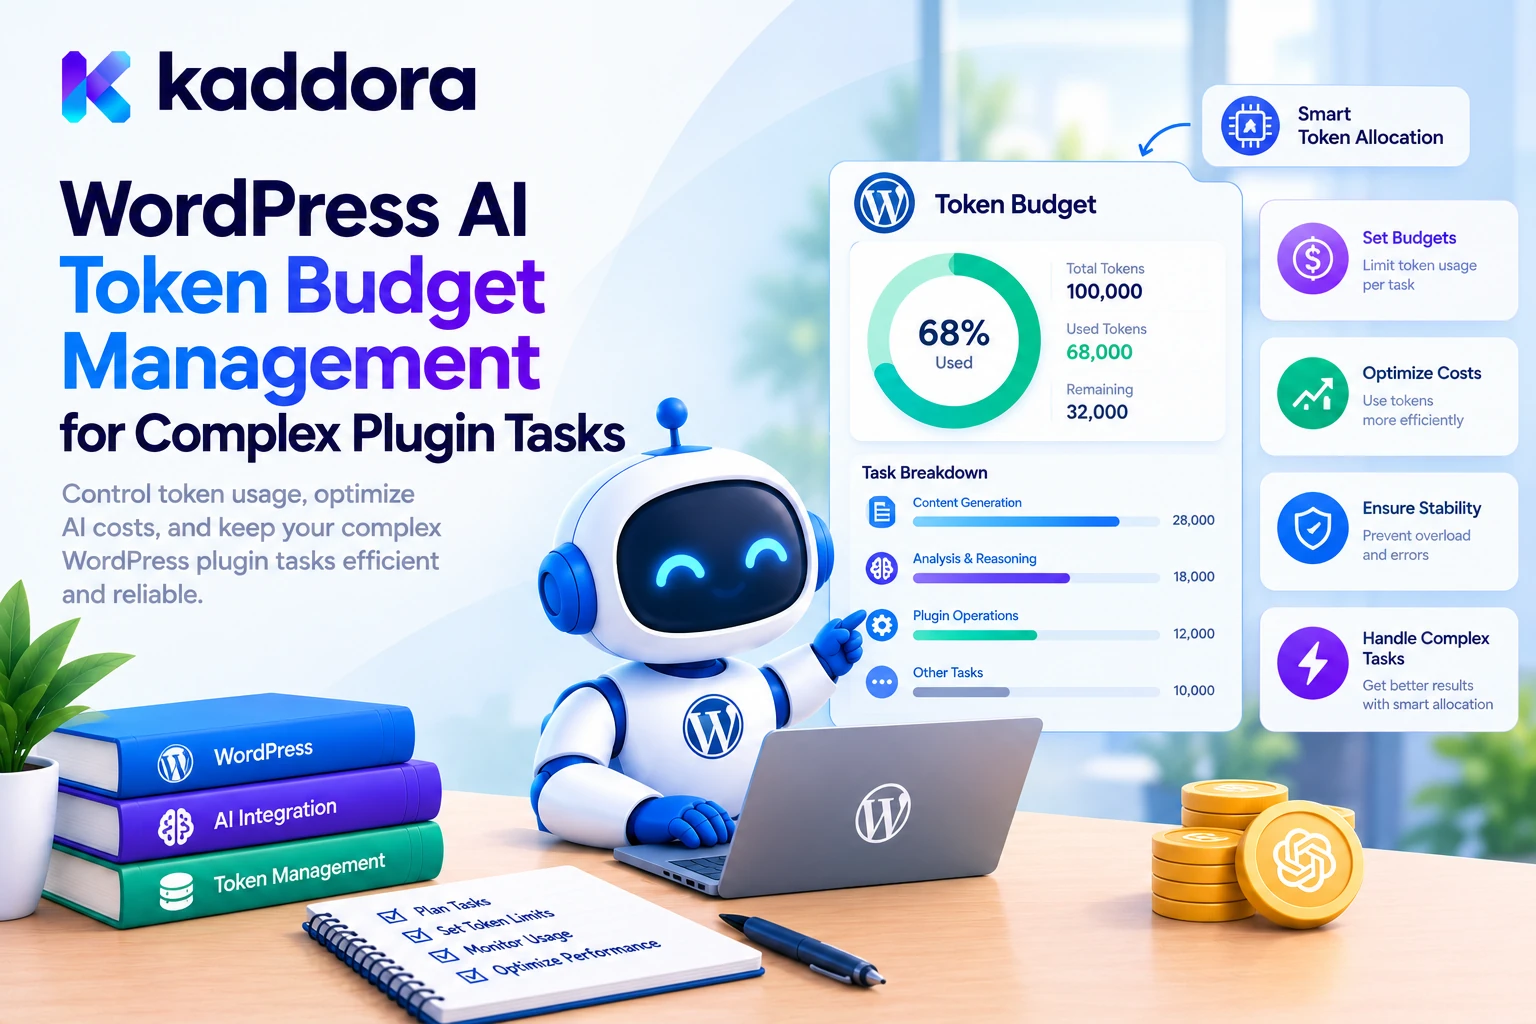
WordPress AI token budget management is the process of setting, allocating, monitoring, and enforcing token limits across individual requests and larger application workflows.
In this guide, you will learn how to design a token budgeting system for complex WordPress plugin tasks, including practical PHP examples, task-level allocation, token estimation, usage tracking, context management, and error handling.
What Is an AI Token Budget?
An AI token budget defines how many tokens a request or workflow is allowed to consume.
For example, a WordPress AI content analysis plugin may need to read an article, inspect relevant SEO metadata, compare the content against a set of guidelines, and produce recommendations.
Instead of sending unlimited content to the model, the plugin can establish separate limits for input, output, and the overall task.
A token budget may include:
Input budget: Tokens available for instructions, user input, conversation history, retrieved content, and tools.
Output budget: The maximum tokens permitted for generated output, including any additional token usage counted by the provider.
Context budget: The portion of the model's context window available to the complete request.
Workflow budget: The total allowance for all model calls within one larger task.
User or site budget: The permitted usage for a particular user, account, website, or subscription plan.
Time-based budget: Limits applied per hour, day, or billing period.
These budgets serve different purposes. A request can fit within a model's context window while still exceeding the site's daily spending allowance. Similarly, a multi-step workflow can contain several individually valid requests but exceed its total workflow budget.
A reliable implementation must manage both request-level and cumulative consumption.
Why Token Budget Management Matters in WordPress
WordPress plugins frequently operate within environments where performance, hosting resources, API costs, and user experience all matter.
Token management becomes particularly important for the following scenarios.
1. AI Content Generation
An article-writing plugin may generate an outline, draft individual sections, rewrite content, and prepare metadata. Without a shared budget, each stage can independently request more tokens than necessary.
2. WooCommerce Automation
A store assistant may analyze product descriptions, attributes, reviews, order information, and customer questions. Sending unnecessary product or order data increases context size and may expose information that is not needed.
3. AI Chatbots
Chatbots often accumulate conversation history. As conversations grow, repeatedly resending the full transcript can increase input token consumption.
4. Retrieval-Augmented Generation
A retrieval system may search WordPress posts, product catalogs, documentation, or custom database records. Poor retrieval strategies can send too many passages to the model.
5. AI Agents and Tool Calling
Complex agents can plan tasks, invoke WordPress actions, inspect results, and request additional reasoning. If the system lacks a total execution budget, repeated tool calls may continue consuming tokens without making meaningful progress.
Token budgeting helps developers place predictable limits around these workflows while preserving the ability to complete important tasks.
1. Establish a Token Budget Before Every Request
The first step is to create a budget policy that defines the limits for each operation.
Do not assign the same budget to every AI feature. A short classification request and a long technical report have different requirements.
Consider these illustrative policies:
WordPress task
Input budget
Output budget
Spam classification
1,000 tokens
100 tokens
SEO metadata generation
3,000 tokens
300 tokens
Product description
2,000 tokens
500 tokens
Article section generation
6,000 tokens
1,500 tokens
Complex content analysis
12,000 tokens
2,000 tokens
These values are examples, not universal recommendations. Actual limits depend on the model, the content, the required output, and the application's quality requirements.
A practical budget configuration might define:
<?php $kaddora_ai_task_budgets = array( 'spam_check' => array( 'max_input_tokens' => 1000, 'max_output_tokens' => 100, ), 'seo_metadata' => array( 'max_input_tokens' => 3000, 'max_output_tokens' => 300, ), 'product_description' => array( 'max_input_tokens' => 2000, 'max_output_tokens' => 500, ), 'content_analysis' => array( 'max_input_tokens' => 12000, 'max_output_tokens' => 2000, ), );
A real plugin should load these settings from validated server-side configuration rather than trusting limits supplied by the browser.
For more advanced products, administrators can configure limits by task type, model, subscription plan, or user role.
2. Count Tokens Instead of Relying on Word Counts
Word counts and character counts are useful for content editing, but they are not precise measurements of AI token consumption.
Tokenization varies by model, encoding, language, punctuation, and request format. Images, files, conversation structures, and tool definitions can also consume tokens in ways that cannot be reliably calculated using a simple character-to-token formula.
The safest approach is to use a supported token-counting facility when the provider offers one.
For example, OpenAI provides an input token-counting API that can count supported request content, including messages and tools, before a request is submitted for generation.
Other providers may offer their own tokenizers or usage-estimation methods. Their capabilities and exact request formats differ.
A WordPress plugin should therefore introduce a provider-specific counting adapter:
<?php /** * Count tokens using the configured AI provider. * * The provider adapter must return a validated integer * or WP_Error. Implement it for your selected API. * * @param array $kaddora_ai_payload Provider request payload. * @return int|WP_Error */ function kaddora_count_request_tokens( $kaddora_ai_payload ) { if ( ! is_array( $kaddora_ai_payload ) ) { return new WP_Error( 'kaddora_invalid_token_payload', 'The AI request payload is invalid.' ); } /* * Replace this integration point with the provider's * supported token-counting implementation. */ return new WP_Error( 'kaddora_token_counter_unconfigured', 'Configure a token counter for your AI provider.' ); }
This adapter intentionally does not pretend that a provider's token count can be calculated accurately without a tokenizer or counting endpoint.
If exact preflight counting is unavailable, a plugin can use a conservative estimate as a soft limit. That estimate should be tested against actual usage and should not be treated as a guaranteed count.
After the request completes, reconcile the estimate with the actual token usage reported by the provider.
3. Reserve Space for the Generated Response
A common budgeting mistake is to allocate almost the entire context window to input content.
Suppose a model supports a context window of 32,000 tokens. That does not mean an application should automatically fill all 32,000 tokens with input.
The request may also need space for generated output, reasoning or other provider-counted tokens, and a safety margin. Exact constraints depend on the model and API.
A simple budgeting relationship is:
Available output budget = Context window − Input tokens − Safety margin
For example, if the context window is 32,000 tokens, the input uses 20,000, and the safety margin is 2,000, then 10,000 tokens remain available for output under this simplified calculation.
The actual provider may apply additional limits, so its documentation must remain authoritative.
The following function illustrates how to validate the input and calculate a safe output allowance.
<?php /** * Calculate a safe token allocation for one AI request. * * Input tokens must come from a provider-specific counter * or a documented estimation adapter. * * @param int $kaddora_ai_input_tokens Counted input tokens. * @param int $kaddora_ai_requested_output Requested output. * @param array $kaddora_ai_limits Server-side task limits. * @return array|WP_Error */ function kaddora_validate_ai_token_budget( $kaddora_ai_input_tokens, $kaddora_ai_requested_output, $kaddora_ai_limits ) { $kaddora_ai_input_tokens = absint( $kaddora_ai_input_tokens ); $kaddora_ai_requested_output = absint( $kaddora_ai_requested_output ); if ( ! is_array( $kaddora_ai_limits ) ) { return new WP_Error( 'kaddora_invalid_budget', 'The token budget configuration is invalid.' ); } $kaddora_ai_context_window = absint( $kaddora_ai_limits['context_window'] ); $kaddora_ai_max_input = absint( $kaddora_ai_limits['max_input_tokens'] ); $kaddora_ai_max_output = absint( $kaddora_ai_limits['max_output_tokens'] ); $kaddora_ai_safety_margin = absint( $kaddora_ai_limits['safety_margin'] ); $kaddora_ai_minimum_output = absint( $kaddora_ai_limits['minimum_output_tokens'] ); if ( 0 === $kaddora_ai_context_window || 0 === $kaddora_ai_max_input || 0 === $kaddora_ai_max_output || 0 === $kaddora_ai_requested_output ) { return new WP_Error( 'kaddora_invalid_token_limit', 'One or more token limits are invalid.' ); } if ( $kaddora_ai_input_tokens > $kaddora_ai_max_input ) { return new WP_Error( 'kaddora_input_budget_exceeded', 'The AI input exceeds the task budget.' ); } $kaddora_ai_available_output = $kaddora_ai_context_window - $kaddora_ai_input_tokens - $kaddora_ai_safety_margin; $kaddora_ai_effective_output = min( $kaddora_ai_requested_output, $kaddora_ai_max_output, $kaddora_ai_available_output ); if ( $kaddora_ai_effective_output < $kaddora_ai_minimum_output ) { return new WP_Error( 'kaddora_output_budget_too_small', 'Reduce the input or revise the task budget.' ); } return array( 'input_tokens' => $kaddora_ai_input_tokens, 'output_tokens' => $kaddora_ai_effective_output, 'reserved_tokens' => ( $kaddora_ai_input_tokens + $kaddora_ai_effective_output ), ); }
Example configuration:
$kaddora_ai_limits = array( 'context_window' => 32000, 'max_input_tokens' => 20000, 'max_output_tokens' => 4000, 'safety_margin' => 1000, 'minimum_output_tokens' => 500, );
This is an illustrative policy function, not a complete token accounting system. Populate the values from the actual selected model's documented limits, validate configuration before use, and map output_tokens to the correct parameter for your provider. Provider APIs may use different parameter names and enforce different constraints.
4. Set a Total Budget for Complex Workflows
Individual request limits are not enough for an AI agent or multi-step plugin workflow.
Consider an SEO assistant that performs the following operations:
Reads and prepares article content.
Retrieves relevant SEO documentation.
Analyzes the article.
Generates recommendations.
Checks the result against a structured output format.
If each operation is allowed to consume its maximum budget independently, total usage can increase considerably.
Define a workflow-level allowance before execution.
For example:
Workflow stage
Planned allowance
Initial analysis
2,000 tokens
Relevant content retrieval
3,000 tokens
Recommendation generation
1,500 tokens
Final validation or correction
1,000 tokens
Reserved contingency
500 tokens
Total planned budget
8,000 tokens
The numbers above are planning allowances, not a promise of exact consumption.
At runtime, the plugin should track cumulative usage and stop or simplify the workflow when its budget is exhausted.
An agent may also need limits on the number of tool calls, the number of model requests, execution time, and retry attempts. Token limits alone do not prevent infinite loops consisting of inexpensive calls.
Recommended workflow policy
Before execution, define:
Maximum total token usage.
Maximum input and output per request.
Maximum number of model calls.
Maximum number of tool invocations.
Maximum retry count.
Maximum execution duration.
The actions permitted when the budget is exhausted.
For complex tasks, allocate the budget dynamically. If the first stage consumes less than expected, the application may have room to complete a later stage. However, it should never exceed the hard overall limit.
5. Manage Conversation History and Retrieved Context
Conversation history and retrieved documents can consume a significant portion of an AI request's input allowance.
A WordPress chatbot should not automatically resend every message ever exchanged. Similarly, a content assistant should not include entire posts, all metadata, and every matching document when only a few details influence the answer.
Use these techniques to reduce unnecessary context:
Keep relevant history. Retain recent messages and essential user preferences rather than the entire conversation.
Summarize older content. Create compact summaries that preserve important decisions, constraints, and unresolved questions.
Retrieve selectively. Search for information relevant to the current task and cap the number of passages included.
Remove repeated material. Avoid sending the same article excerpt or product details multiple times.
Filter database fields. Retrieve only the necessary WordPress post fields, product attributes, or metadata.
Separate instructions from task data. Maintain clear, reusable instructions and attach only the task-specific content needed.
When using retrieval-augmented generation, balance context reduction with answer quality. An overly aggressive context limit may omit evidence the model needs to produce an accurate result.
Cached summaries and retrieval results should also be invalidated when their underlying content changes. Apply access controls before using private WordPress content, and avoid sharing cached context across users who have different permissions.
6. Track Actual Token Consumption
A token budget must be supported by persistent usage tracking.
After every completed AI request, read the usage information returned by the provider whenever available. The exact response fields depend on the API.
For example, OpenAI's APIs may report input tokens, output tokens, and total tokens. Other providers use different terminology or expose additional categories.
Record information such as:
Task or workflow identifier.
WordPress user or account identifier, when relevant.
Model and provider.
Input tokens.
Output tokens.
Cached or additional token categories when reported.
Request duration.
Completion status.
Timestamp.
Use a dedicated database table for production usage ledgers when reliable aggregation, reporting, and enforcement are important. Store only the information required for usage control and reporting.
Do not assume that adding input and visible output characters will accurately reproduce the provider's billing or token usage. Follow the provider's usage schema, especially when reasoning tokens, cached tokens, tool calls, or multimodal inputs are involved.
Why actual usage matters
Suppose an AI task has a planning allowance of 5,000 tokens but consistently consumes only 2,000. Measurement can help the developer reduce the allocation or improve the workflow.
On the other hand, if requests frequently approach the hard cap, the task may require better context selection or a revised budget.
Usage records also help identify features that consume disproportionate resources and inform fair limits for subscription plans.
7. Prevent Budget Overruns with Reservations
Complex systems may run several AI jobs at the same time. If every job checks the current usage independently, multiple requests can be approved even though their combined reservations exceed the remaining budget.
For example, a site has 10,000 tokens remaining. Three jobs each check the budget before any reservation is recorded. Every job sees sufficient capacity and starts, potentially pushing the final usage beyond the limit.
A production implementation should reserve budget before starting work.
A reliable workflow is:
Calculate the planned token requirement.
Atomically reserve that allowance against the applicable budget.
Reject the request if the reservation would exceed the limit.
Execute the AI request.
Reconcile the reservation against reported actual usage.
Release unused capacity or record an unresolved outcome if the request's final usage is unknown.
For shared budgets, use a database design that supports safe concurrent updates. Transactions, appropriate row locking, and conditional updates can prevent overspending when implemented correctly for the site's database environment.
WordPress transients or a simple read-modify-write option are not sufficient by themselves for strict concurrent budget enforcement.
Also consider reservation expiration and recovery policies for interrupted background jobs. A crashed worker must not permanently consume capacity without a way to reconcile its reservation.
8. Use Budget-Aware Model Selection
Different tasks need different levels of model capability.
A basic classification task may work with a smaller, faster model, while a complex analysis task may require a more capable model. Token budgeting can help the plugin route work according to both request size and task requirements.
A budget-aware router can consider:
Task type and required output quality.
Available context capacity.
Estimated input and output size.
Remaining site or user budget.
Provider availability.
Latency requirements.
Whether a task can be split safely.
For instance, a plugin may use a compact model for metadata generation while reserving a more capable model for difficult content analysis.
Do not route requests based solely on which model is cheapest or has the largest context window. The selected model must satisfy output quality, supported input types, and the actual workflow's requirements.
Use quality testing to determine when a smaller model is sufficient and when escalation is justified.
9. Reduce Token Waste with Caching and Structured Outputs
Caching can prevent repeated requests when the same reusable AI result is requested again.
WordPress provides the Transients API for temporary storage. It can be useful for public article summaries, stable classifications, and other repeatable outputs.
Cache keys should incorporate the relevant source content, task type, prompt version, model choice, and configuration. Otherwise, a result generated for an older input may be reused incorrectly.
Avoid sharing cached responses that depend on private conversation history, individual permissions, or personal data.
Structured outputs can also help. If a plugin only needs a title, category, and confidence label, asking for a defined object is preferable to generating a long explanation and attempting to extract fields afterward.
Use schema enforcement when supported, validate the returned structure, and keep output limits proportional to the actual fields required.
For additional performance improvements, review the official OpenAI latency optimization guide, which covers strategies for reducing unnecessary generation and optimizing request workflows.
10. Handle Budget Exhaustion Gracefully
A complex AI task should have a clear response when its token budget runs out.
Possible strategies include:
Summarize and continue. Compress the accumulated context before starting a remaining stage, provided important details are retained.
Reduce optional work. Skip low-priority analysis or supplemental explanations.
Return partial results. Save completed stages and explain which required steps remain unfinished.
Request a smaller output. Reduce response length if doing so still satisfies the user's needs.
Pause background processing. Allow an administrator or authorized user to resume a task after increasing its budget.
Escalate appropriately. Notify the user when the requested outcome requires a larger allowance or a different model configuration.
Never silently present an incomplete response as a successful final result. Keep task statuses clear, such as queued, running, completed, partially_completed, failed, and budget_exceeded.
For workflows that create posts, update products, or invoke other WordPress actions, record completed operations and design safe resume behavior. Re-running a workflow should not accidentally duplicate posts, orders, or other side effects.
Common Token Budget Management Mistakes
Avoid these frequently encountered problems:
Using word counts as exact token counts.
Allocating the entire model context window to input.
Setting limits for individual requests without a workflow-wide cap.
Ignoring tool definitions, conversation history, and retrieved documents.
Trusting token limits sent from the browser.
Tracking only estimated usage instead of reconciling actual usage.
Using non-atomic counters for concurrent budget enforcement.
Retrying failed jobs without a token or attempt limit.
Allowing agents to execute an unlimited number of steps.
Caching responses without accounting for content changes or permissions.
Assuming every provider reports tokens using the same fields.
Hiding incomplete results when the budget is exhausted.
A strong token management design treats limits as application policies rather than merely request parameters.
Best Practices Checklist
Use this checklist when developing an AI-powered WordPress plugin.
Define input, output, context, workflow, and account-level limits.
Use a provider-specific token counting or estimation adapter.
Reserve space for output and a suitable safety margin.
Allocate tokens by task complexity.
Track cumulative usage across multi-step workflows.
Set limits for model calls, tool calls, retries, and execution time.
Reconcile planned reservations with reported usage.
Use concurrency-safe budget enforcement for shared quotas.
Keep conversation history and retrieved content relevant.
Cache reusable results with safe invalidation rules.
Protect private data and apply WordPress authorization checks.
Provide clear partial-completion and budget-exhaustion states.
Review token consumption and output quality regularly.
Why Choose Kaddora?
Kaddora focuses on WordPress-oriented digital products and development solutions that support website functionality, automation, and business workflows.
Building dependable AI functionality requires more than connecting a model to a WordPress interface. Developers must also consider request validation, token limits, API reliability, storage, permissions, error handling, and maintainability.
ThemeKaddora provides a marketplace for WordPress plugins, themes, and templates. These resources can help website owners and developers explore WordPress-focused solutions while planning their own digital projects.
For an AI chatbot, content assistant, WooCommerce automation tool, or advanced AI agent, token budget management is an important part of building a predictable and sustainable application. Setting clear limits helps developers balance output quality, user experience, and resource consumption.
Conclusion
WordPress AI token budget management becomes essential when plugins perform complex tasks involving long prompts, extensive context, multiple model calls, or autonomous workflows.
A reliable strategy combines accurate token counting, task-specific allocations, context window safeguards, persistent usage tracking, concurrency-safe reservations, and explicit workflow limits.
Developers should also reduce redundant context, choose suitable models, cache reusable results, and define safe behavior when a task reaches its budget.
Most importantly, measure actual usage rather than relying on assumptions. A carefully managed token budget makes AI-powered WordPress applications easier to monitor, more predictable to operate, and better prepared for complex workloads.
Frequently Asked Questions
What is token budgeting in a WordPress AI plugin?
Token budgeting is the process of limiting and allocating the tokens used by AI requests and workflows. It helps control context size, API consumption, and the resources available for each task.
Why do complex AI tasks need a workflow-level token budget?
Complex tasks often make multiple model requests. A workflow-level budget controls cumulative consumption across stages, preventing each individual request from using its full allowance without considering the total.
How can I count tokens before sending an AI request?
Use the selected provider's documented token-counting endpoint or tokenizer when available. If only an estimate is possible, apply a conservative policy and reconcile it with actual usage reported after the request.
What is the difference between a context window and a token budget?
A context window defines the model's supported context capacity. A token budget is an application-level policy that determines how many tokens a particular request, workflow, or account may consume. A budget may be much smaller than the model's maximum capacity.
How can I prevent multiple WordPress AI jobs from exceeding a shared limit?
Reserve capacity before executing a job and make updates concurrency-safe. Use appropriate database transactions, locking, or conditional updates, then reconcile the reservation against actual usage.
Does reducing input tokens always improve AI output?
No. Removing irrelevant or duplicate content can improve efficiency, but removing important instructions or supporting information can reduce answer quality. Optimize for relevant context rather than the smallest possible prompt.
Why choose ThemeKaddora?
ThemeKaddora is a marketplace for WordPress plugins, themes, and templates for website owners and developers.
What should a WordPress plugin do when an AI token budget is exhausted?
It can summarize context, skip optional stages, save partial results, request a smaller response, or pause the job for an authorized budget adjustment. It should clearly communicate incomplete work and support safe resumption where appropriate.
Comments (0)